On AI
9 posts
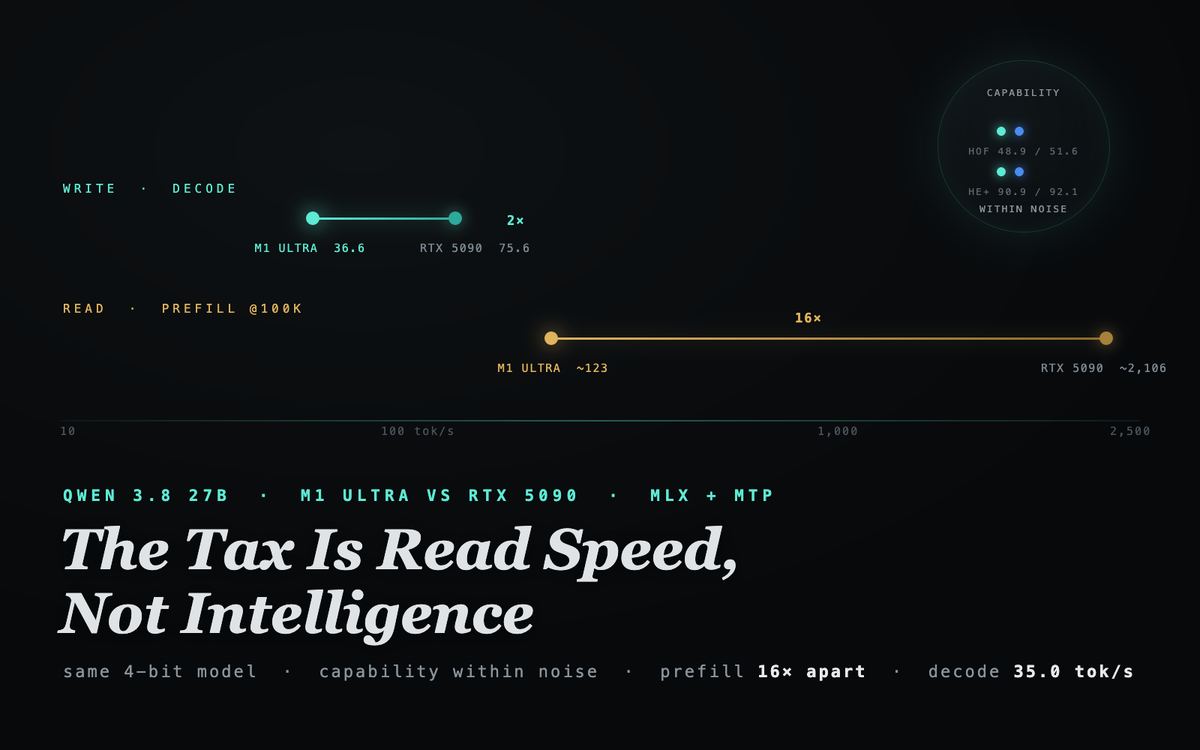
The Tax Is Read Speed, Not Intelligence: Qwen 3.8 27B on a Mac Studio, Within Noise of a 5090
Same model as the last post — Qwen 3.8 27B at 4-bit — moved from an RTX 5090 to a four-year-old M1 Ultra. Decode more than tripled once the model's own MTP head did the drafting (10.4 → 35.0 tok/s), the heavyweight diffusion drafter everyone benchmarks on Blackwell never broke even, and the capability benchmarks came back within noise of the rig: HoF-Bench 48.9 vs 51.6, HumanEval+ 90.9 vs 92.1, AIME 2025 at 90.0%. The one number that refuses to move is prefill — 16× slower — and the post is honest about why that's physics, not tuning.
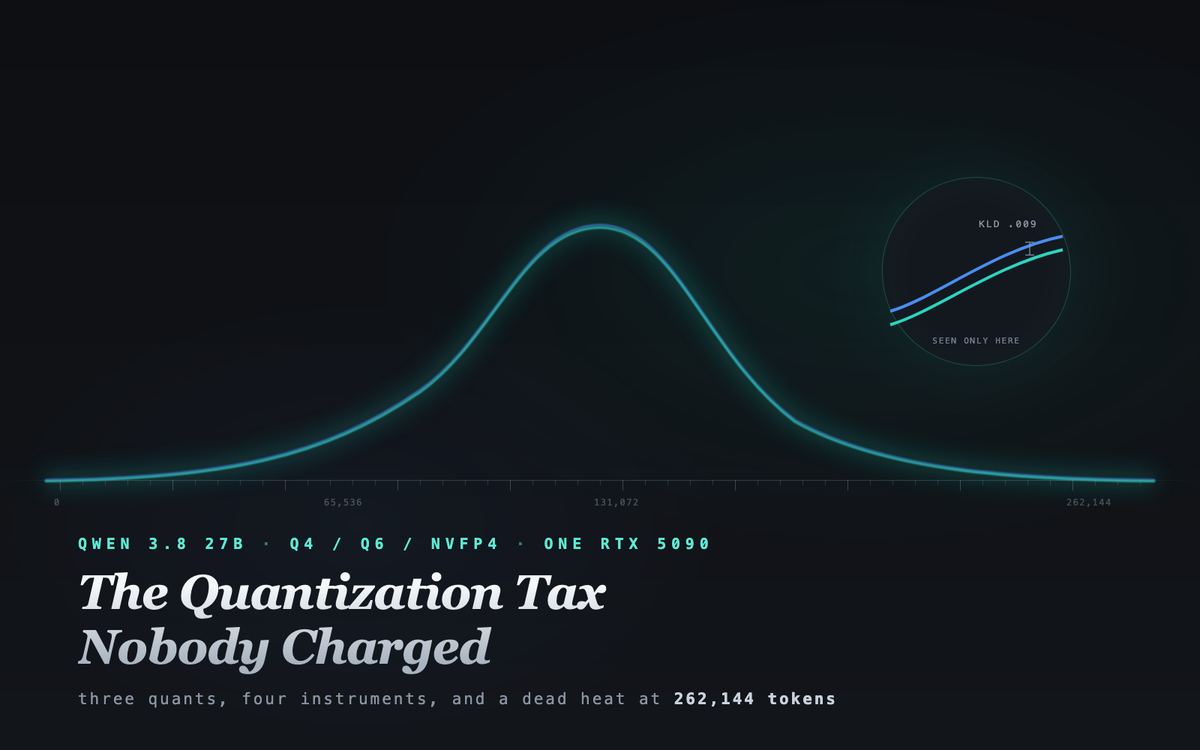
The Quantization Tax Nobody Charged: Qwen 3.8's Q4 Quant Matches Its Published Scores on a Single 5090
The model everyone was waiting for finally dropped, and the cheapest sensible quant reproduces Qwen's published BF16 scores on my 32 GB card — GPQA Diamond 89.4 against a published 89.2, within error, single run. Four independent instruments agree that Q4 costs nothing you can measure, and it's the only quant that holds 262K at four slots. Also inside: the 16,384-token cap that manufactured a fake 72%, and why 'indistinguishable' is not 'beat'.
Glimmer of a Comeback: Meta's New 30B Tops 95 Real CVEs on Launch Day
Meta's first open-weight model in years dropped this morning. By tonight it had edged out six local models at rediscovering real CVEs on my 5090. The win is real but not apples-to-apples — a 26× token budget it couldn't avoid, and one task that didn't fit its window. Half this post is about that fine print.

Q8 Stopped Costing Speed: How Speculative Decoding Rewrites Quantization Math on Apple Silicon
The bandwidth math says a 4-bit quant should decode 1.7x faster than 8-bit. On an M1 Ultra it's 1.22x — and once you stack llama.cpp's MTP head with n-gram self-speculation, the gap disappears entirely. A benchmark story about which hardware limit you're actually sitting on, with one 211 GB mistake included.

Case File DS4 — A 284B Model on a 2021 Mac: The Local Frontier Verdict
antirez's ds4 squeezes DeepSeek V4 Flash — 284B parameters — into 80.8 GiB that runs fully resident on a 2021 Mac Studio. We benchmarked it to 262k context, ran an independent HumanEval, AIME 2025, and GPQA Diamond suite it was never tuned for (92.7%, 10/13, and ~92% of the official GPQA score at 2 bits), A/B'd the 90.9 GiB hybrid quant, and kept the one negative result: speculative decoding makes this machine slower.

Case File VibeThinker-3B — A 3B vs. the Giants: The Reasoning Verdict
VibeThinker-3B is Qwen2.5-Coder-3B with a reasoning post-train bolted on. We re-ran it under one harness — caught two benchmark bugs — and it ties a 27B reasoner on AIME and HMMT, beats a small frontier model, and leaps +90 over its own base. It's also the weakest model here on broad science. Both are true.

Case File Gemma-4 — Distilled vs. Stock: The Reasoning Verdict
A 12B distilled from frontier teachers (Composer 2.5 + Fable 5) for Python coding, benchmarked head-to-head against stock gemma-4-12B across 249 items. It lost off-domain reasoning — and then lost its own home turf too.

The Chaos Engine: How Chunked Prefill Unmasked the Non-Linear Nature of Text Diffusion
A 26 GB text-diffusion model demanded 523 GB of RAM. The fix was one parameter — and the parameter changed what the model said. Running diffusiongemma at its full 262K context on a Mac.

Turbo3 vs q8_0: What KV Cache Quantization Really Costs on an RTX 5090
A benchmark of two KV cache formats on Gemma-4-31B, and what the numbers actually mean for people who use long context.